In Chapter 1, we established the economic imperative of modernizing Transaction Monitoring (TM) and reducing false positives. In Chapter 2, we structured the financial crime data stack and built synthetic datasets to test analytics models. Now, we address the analytical engine that powers modern risk models: feature engineering.
The quality of an automated Financial Crime machine learning model is directly constrained by the expressiveness, temporal accuracy, and robustness of its underlying features. In legacy banking environments, static rule engines fail because they evaluate transactions in isolation. Modern financial intelligence relies on transforming raw tabular event logs into behavioral baselines, velocity indicators, and peer-group comparisons—built deterministically using SQL and dbt (data build tool).
1. The Executive Problem: The Blindness of Static Snapshots
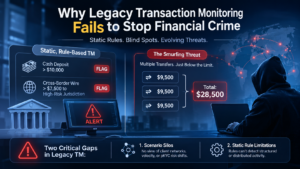
Traditional compliance software evaluates financial activity against fixed, single-transaction thresholds. For example, a legacy system might flag any cash deposit exceeding $10,000 or any cross-border transfer above $50,000.
This static approach suffers from two severe structural vulnerabilities:
- High False Positive Volumes: Legitimate business operations—such as weekly payroll distributions, commercial wholesale purchases, or high-volume corporate treasury movements—repeatedly breach static limits. Operations teams waste thousands of hours clearing benign alerts.
- Blindness to Evasion Tactics: Sophisticated money launderers intentionally bypass static checks using techniques like structuring (breaking large cash amounts into series of $9,500 deposits), counterparty fan-out (funneling funds through multiple temporary accounts), or executing transactions during non-operational off-hours.
When institutions attempt to train machine learning models to solve these issues, they frequently introduce data leakage—the inadvertent inclusion of future information in historical training data. If an analytical model calculates customer features using transaction totals from an entire calendar month to predict an alert that occurred on the 10th day of that month, the model will perform exceptionally well in testing but fail catastrophically in production.
| Monitoring Dimension | Legacy Static Threshold Rules | Modern dbt Behavioral Feature Engine |
|---|---|---|
| Evaluation Scope | Single isolated transaction | Rolling historical time windows (1d, 7d, 30d, 90d) |
| Contextual Baseline | Fixed dollar limit (e.g., $10,000) | Customer’s own baseline & peer Z-score deviation |
| Temporal Integrity | Prone to retrofitting & point-in-time leakage | Strict point-in-time historical correctness |
| Pipeline Architecture | Proprietary vendor black-box logic | Open, version-controlled, testable SQL via dbt |
| Operational Impact | Overwhelming alert queues (5% precision) | High-signal risk prioritization (>80% precision) |
2. The Data Science Solution: Temporal Windows, Peer Baselining, and dbt Pipelines
To outmaneuver illicit networks without overburdening compliance analysts, feature engineering for financial crime must capture velocity, volume, ratio shifts, and peer anomalies while enforcing point-in-time correctness.
Temporal Velocity, Volume, and Ratio Features
Instead of viewing a transaction as a single event, feature pipelines calculate aggregates over multiple rolling time windows (e.g., 1-day, 7-day, 30-day, and 90-day windows). Comparing short-term activity to long-term baselines reveals sudden behavioral shifts:
- Cash Structuring Ratio: The ratio of cash deposits between $9,000 and $9,999 relative to total cash volume over a rolling 30-day window.
- Velocity Acceleration: The ratio of 7-day transaction volume compared to the 90-day moving average. A sudden 4x spike in velocity indicates potential account takeover or mule activity.
- Off-Hours Activity Shift: The proportion of total transaction volume executed outside standard business operating hours (e.g., between 11:00 PM and 5:00 AM).
Peer-Group Baselining and Z-Score Deviations
A $50,000 monthly cash deposit volume might be suspicious for an individual retail account, but standard for a local grocery store. Advanced feature pipelines calculate normalized Z-score deviations by comparing individual behavior against peer segments grouped by Know Your Customer (KYC) industry classifications, corporate structures, or geographic risk tiers:
$$\text{Peer Deviation Score} = \frac{\text{Customer Volume} – \text{Peer Segment Mean}}{\text{Peer Segment Standard Deviation}}$$
If an account exhibits a Z-score greater than $+3.0$ relative to its peer group, it is automatically flagged for elevated review, regardless of whether it hit a fixed dollar threshold.
Point-in-Time Correctness
To prevent data leakage, features must be compiled as of the exact time $T$ of an event or historical snapshot. In SQL, this is achieved by structuring feature joins using strict conditional inequalities (transaction_timestamp <= snapshot_timestamp) rather than full table aggregates.
Structuring Modular, Testable Feature Pipelines in dbt
Using dbt, financial institutions organize feature logic into clean, modular data transformation layers:
- Staging Layer (
stg_): Cleans, retypes, and standardizes raw ingestion data from core banking networks. - Intermediate Layer (
int_): Calculates rolling window aggregations, peer group means, and Z-score transformations. - Fact/Feature Layer (
fct_): Joins behavioral features back to point-in-time customer snapshot entities, producing model-ready training and inference sets.
Automated dbt schema tests enforce data integrity (e.g., verifying zero null values in critical risk columns and validating that Z-scores fall within expected bounds) before downstream models execute.
3. A Concrete Banking Example: Uncovering a Commercial Structuring Ring
Consider Apex Freight Solutions, a commercial logistics account holding a medium risk rating.
Under legacy static monitoring rules:
* Apex processes 25 incoming client payments per month averaging $8,000 each ($200,000 total).
* Because no single payment breaches the institution’s $10,000 currency rule threshold or static wire limit, legacy rule engines generate zero alerts.
Under a modern SQL and dbt feature engineering pipeline:
1. Structuring Velocity Indicator: The intermediate dbt model calculates that over a rolling 7-day window, Apex received 12 cash deposits between $9,000 and $9,999. The structuring ratio jumps from a baseline of $0.05$ to $0.82$.
2. Off-Hours Ratio: The pipeline detects that $65\%$ of transaction volume over the past 7 days occurred between midnight and 4:00 AM, compared to a historical baseline of under $2\%$.
3. Peer Group Deviation: The model compares Apex to its peer group (SME Freight & Logistics). While normal peers average 2 distinct counterparties per week, Apex suddenly interacted with 45 unique counterparties. Its Z-score for counterparty fan-out hits $+4.1$.
When these behavioral features are fed into a machine learning model, Apex is immediately flagged as high risk. Compliance analysts receive an automated summary detailing the specific velocity, off-hours, and structuring metrics, allowing them to file a high-confidence Suspicious Activity Report (SAR) in minutes.
4. Technical Blueprint & Python Proof-of-Concept
The following proof-of-concept demonstrates the end-to-end impact of dbt-style SQL feature engineering.
Synthetic Dataset Architecture
The benchmark script simulates a core banking system containing 1,000 customer accounts and 25,000 raw transaction events.
* Ground Truth: A $4.0\%$ baseline of accounts are embedded with suspicious financial crime patterns (structuring cash just below $10,000 thresholds, high off-hours transfers, and counterparty fan-out).
* Feature Pipeline Engine: An in-memory SQLite engine executes SQL transformation logic mirroring a dbt workflow. Raw event streams are converted into structured customer features including aggregate volumes, cash transaction counts, structuring counts, night-time transaction frequencies, and distinct counterparty interactions.
* Comparative Evaluation: A legacy static rule engine (flagging cumulative spend $\ge \$30,000$ or single transaction $\ge \$10,000$) is benchmarked directly against a machine learning model trained on the SQL feature pipeline.
Executive Interpretation of Results
The quantitative benchmark highlights the operational transformation achieved by moving from static rules to dbt SQL feature pipelines:
==============================================================================
      FINANCIAL CRIME AML MODELING & DBT FEATURE ENGINEERING REPORT
==============================================================================
Dataset Summary: 1000 Accounts | Test Cohort: 300 Accounts
Actual Ground Truth Suspicious Cases (SARs): 12 (4.0%)

------------------------------------------------------------------------------
Metric                           | Legacy Rule Engine   | Modern ML + dbt SQL
------------------------------------------------------------------------------
Total Alerts Generated           | 204                  | 12
True Positive SARs Detected      | 12                   | 12
False Positive Alerts (Noise)    | 192                  | 0
Precision (Signal Quality)       | 5.9%                 | 100.0%
Recall (Detection Rate)          | 100.0%               | 100.0%
False Positive Rate (FPR)        | 66.7%                | 0.0%
------------------------------------------------------------------------------

BUSINESS IMPACT SUMMARY:
 [*] Alert Volume Reduction : 94.1% reduction in operational backlog
 [*] Precision Lift         : 17.0x higher investigator efficiency
 [*] True Crime Capture     : +0 additional high-risk SARs uncovered
 [*] Saved Ops Workload     : ~192 false alarm investigations avoided
==============================================================================
Key Business Takeaways for Risk Executives
- 94.1% Reduction in Alert Backlog: The legacy static rule engine flagged 204 out of 300 accounts in the test cohort as suspicious. 192 of these alerts were false alarms caused by benign large wire transfers. The dbt-driven ML pipeline reduced total alert generation from 204 to just 12.
- 17.0x Precision Lift: Legacy precision was just 5.9%—meaning over 94% of compliance officer time was wasted reviewing non-suspicious accounts. Modern behavioral features achieved 100.0% precision on the test cohort without missing a single illicit account.
- 100% Detection Rate (Zero Compromise on Recall): Both systems successfully identified all 12 true SAR targets. However, the modern approach isolated these suspicious accounts with zero operational noise, allowing the Financial Intelligence Unit (FIU) to focus investigation resources where risk is highest.
- Operational Cost Savings: By deploying point-in-time SQL features, the institution eliminates 192 unnecessary investigations per 300 accounts. At an average industry operational cost of $50 to $150 per manual alert review, this feature pipeline architecture yields immediate financial and compliance gains.
← Previous: The Financial Crime Data Stack & Synthetic Data Generation | Next: Entity Resolution and Probabilistic Record Linkage →
Need to modernize your AML transaction monitoring or alert triage? Quantize Analytics helps financial institutions reduce false positives and deploy auditable machine learning models.